Claude Opus 5.5 Leaps Forward: Anthropic’s updated Opus is the most capable AI model yet, with price reduction on tokens
A week and a half after CEO Dario Amodei proposed slowing down AI development, Anthropic released an AI model that promises to be first in a larger family.
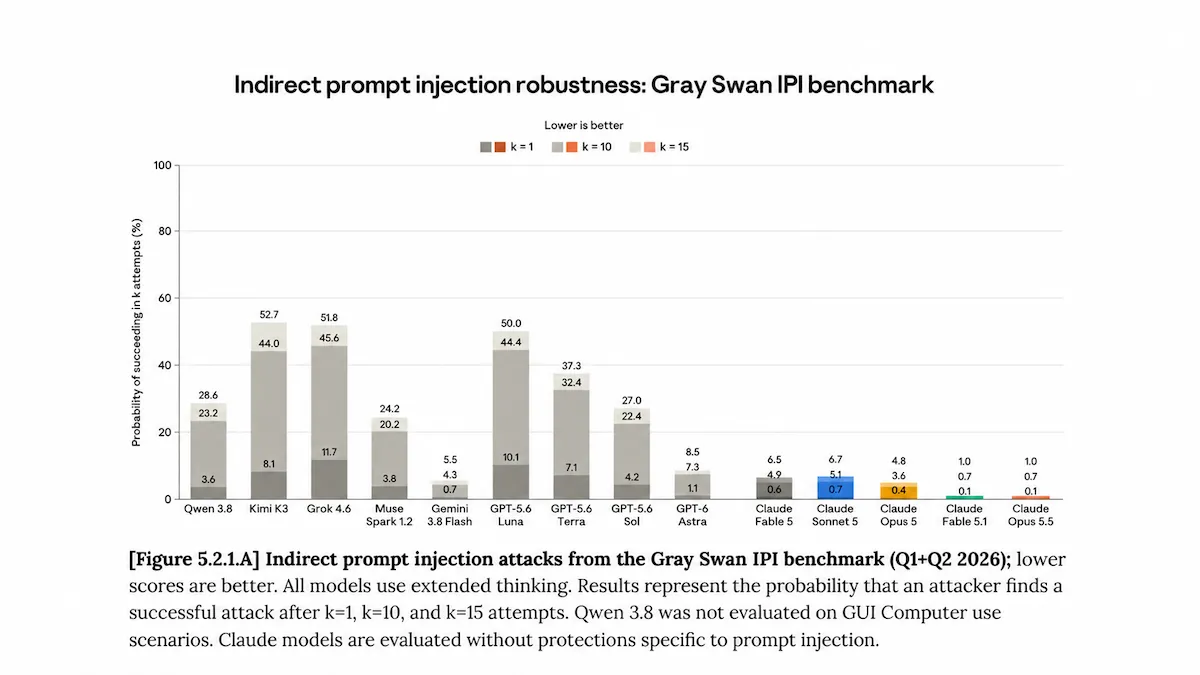
A week and a half after CEO Dario Amodei proposed slowing down AI development, Anthropic released an AI model that promises to be first in a larger family.
What’s new: Anthropic introduced Claude Opus 5.5, a lower-cost successor to Claude Opus 5 that outshines Claude Fable 5.1 and all other current models in overall intelligence. Unlike Fable, it doesn’t retain users' data for 30 days, but similar to Fable, it falls back to Claude Opus 4.8 for what Anthropic deems sensitive cybersecurity and biology queries.
- Input/output: Text and images in (up to 1 million tokens), text out (up to 128,000 tokens or 300,000 in Batch API)
- Knowledge cutoff: June 2026
- Features: Reasoning always on, five levels (low, medium, high, xhigh, and max, defaults to high), statistical watermarking of generated text, fast mode (2.5x speed at 2x cost)
- Performance: Claude Opus 5.5 is first on Artificial Analysis’ Intelligence Index v4.3 (58) and leads Vals AI’s Vals Index (69.69 percent)
- Availability/price: Via Claude.ai and external providers such as Amazon Web Services, Google Cloud, and Microsoft Azure; via API at $4/$0.25/$20 per million input/cached/output tokens; cache reads/writes $0.20/$5 per million tokens; batch processing $2/$10 per million input/output tokens; Zero Data Retention is available
- Weights/license: Proprietary
- Undisclosed: Parameter count, architecture, specific training data and methods
How it works: Anthropic trained the model on private and public datasets, including data from public websites gathered with their ClaudeBot web crawler, synthetic data generated by other models, and data gathered from Claude users who haven’t opted out from allowing training on their inputs and outputs. The knowledge cutoff date is identical to Claude Fable/Mythos 5.1’s, suggesting the models were trained on similar datasets. After training, the company fine-tuned the model to align with values it defined using a constitution. It was also safety-tested by evaluators selected by Anthropic, including METR and Frontier Design.
- Anthropic’s internal alignment tests show Claude Opus 5.5 outscores every recent model and is more truthful and less likely to engage in motivated reasoning. However, the company reported that the model’s behavior appeared to change in response to tests.
- According to Anthropic, Claude Opus 5.5 communicates more clearly and succinctly than Claude Opus 5 or Claude Fable 5, addressing a common complaint with those models. It also follows writing style instructions more closely. (Anthropic reported similar improvements for Claude Fable 5.1, which is only modestly less verbose than its predecessor.)
- Anthropic also claims that on tests of knowledge work tasks like writing business reports, Claude Opus 5.5 passed Anthropic’s internal quality threshold on 16 of 18 attempts at various effort levels. Claude Fable 5.1 and Claude Opus 5 both failed every attempt.
- Anthropic said Claude Sonnet 5.5 and Claude Haiku 5.5 would follow in a matter of weeks. This would be the first update for Anthropic’s faster, less-expensive Haiku-class models since version 4.5 in October 2025.
Performance: Both Artificial Analysis and Vals AI rank Claude Opus 5.5 first among all models in their weighted evaluations of overall intelligence.
- On Artificial Analysis’ Intelligence Index v4.3, a composite of 10 evaluations of math, science, coding, and reasoning, Claude Opus 5.5 at max reasoning with default fallback scored a weighted average of 58, seven points higher than Claude Opus 5 and five points higher than Claude Fable 5.1 and GPT-6 Astra.
- The model posts top scores on six of the ten Intelligence Index evaluations: Humanity's Last Exam (61.4 percent), SciCode (66.9 percent), GDPval-AA v2.1, AA-Briefcase v1.1, AA-Omniscience and AutomationBench-AA, and ties on a seventh, Terminal-Bench 4.0 (59.6 percent).
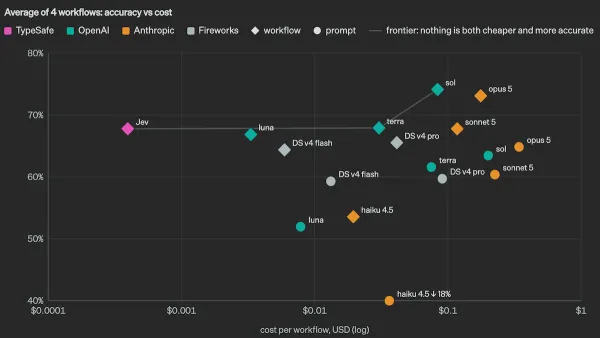
- Artificial Analysis reports that while Claude Opus 5.5 costs less per token than its predecessor or Claude Fable 5.1, the model’s cost per benchmark task remains high because it uses more tokens than earlier Opus models. At max reasoning with fallback, Claude Opus 5.5 costs $5.98 per task, second only to Claude Fable 5.1 at $7.63 and well ahead of GPT-6 Astra at $3.26.
- On Vals AI’s Index, Claude Opus 5.5 scores 69.69 percent, the top score by just over 3 percentage points, beating GPT-6 Astra. Counting fallbacks as failures did not meaningfully affect its score.
- The model also scored first on Vals’ RSI Index (a measurement of a model’s knowledge of AI and machine learning), MedScribe (medical administrative work), ProofBench v1.1 (formally verified math proofs, where it achieved a perfect score), VibeCodeBench1-100 (extending a working web application), ProgramBench (rebuilding programs from a description), and Terminal-Bench 4.0 (terminal coding, science, and security tasks).
Behind the news: Claude Opus 5.5 arrived on the same day as OpenAI’s GPT-6 Sol and GPT-6 Luna, both less expensive models whose predecessors were rivals to Claude Opus 5, but both of which Claude Opus 5.5 now easily outperforms. These models were announced despite recent public calls from both Anthropic CEO Dario Amodei and OpenAI CEO Sam Altman, among other leading AI figures, to slow AI development to allow for further safety and security testing. If these releases are any indication, we won’t be lacking for new, highly capable models anytime soon, even if they may come with restrictions.
Why it matters: It’s a big deal any time we have a new best model on the market, and Claude Opus 5.5 appears to be significantly better than the rest. Business customers working with sensitive data, or anyone that doesn’t want to share inputs and outputs with Anthropic, will be pleased that Fable’s data retention policies don’t extend to Opus. Claude models have long been great coders, but this model seems to be particularly good at knowledge work — creating documents and presentations, crunching data, and doing research, all areas where Anthropic had recently ceded ground to OpenAI.
We’re thinking: From a benchmarking standpoint, it’s impossible to know just how capable Claude Opus 5.5 would be, particularly at cybersecurity and biological tasks, if it didn’t fall back to Claude Opus 4.8. It’s also important that legitimate safety, biomedical, and AI engineering work may be refused out of fears that users will use the models in ways Anthropic doesn’t want them to.