LLMs Can Fine-Tune Neural Networks: Researchers used GPT-6 Astra to improve a small model’s performance by editing its weights
Research suggests that you can improve a neural network’s weights simply by prompting an LLM — for networks of less than 1 billion parameters, at least.
Research suggests that you can improve a neural network’s weights simply by prompting an LLM — for networks of less than 1 billion parameters, at least.
What’s new: Rikiya Takehi, Jayden Teoh, and colleagues from MIT showed that GPT-6 Astra can interpret, improve, and produce neural network weights in proof-of-concept studies.
How it works: The authors asked GPT-6 Astra to (a) identify which game a network was trained on based on its weights, (b) alter the weights of a network to improve its ability to operate a simulated car, and (c) generate a network that would win a game. In a more practical experiment, they asked GPT-6 Astra to improve Qwen3.5-0.8B’s math performance.
- The authors trained four tiny vanilla neural networks (17,000 parameters each) separately to play Breakout, Pong, Pac-Man, and Frogger. Given the weights and asked “Which game was this neural network trained on?” GPT-6 Astra was able to identify the game in all four cases.
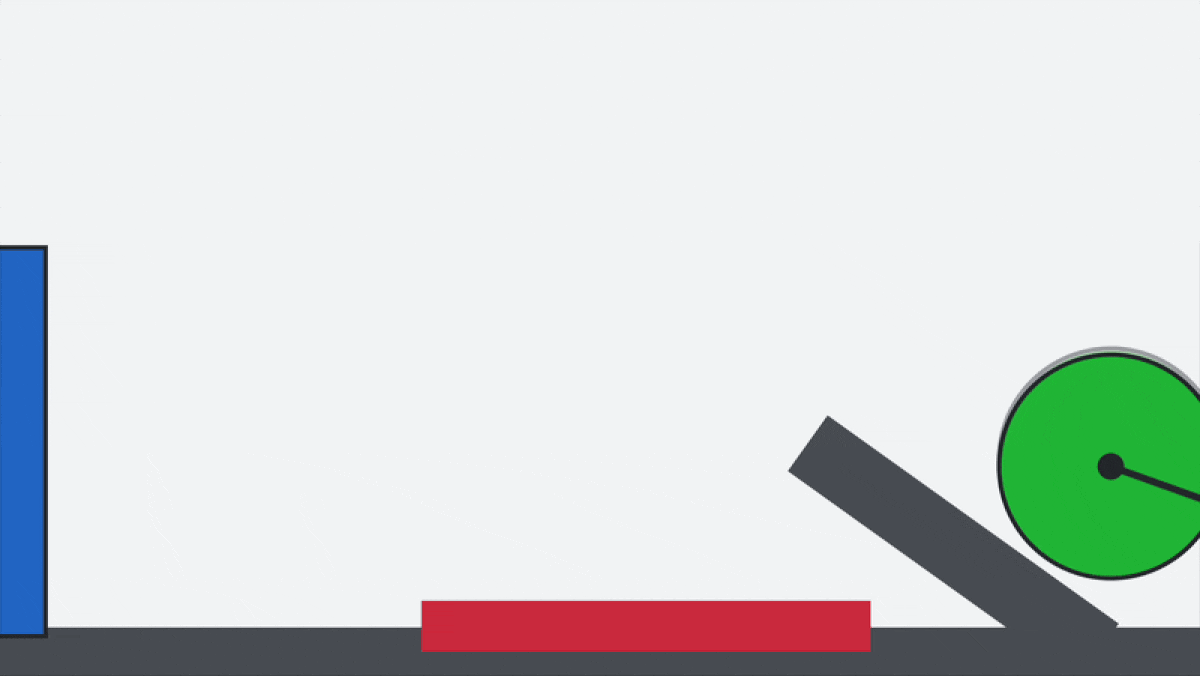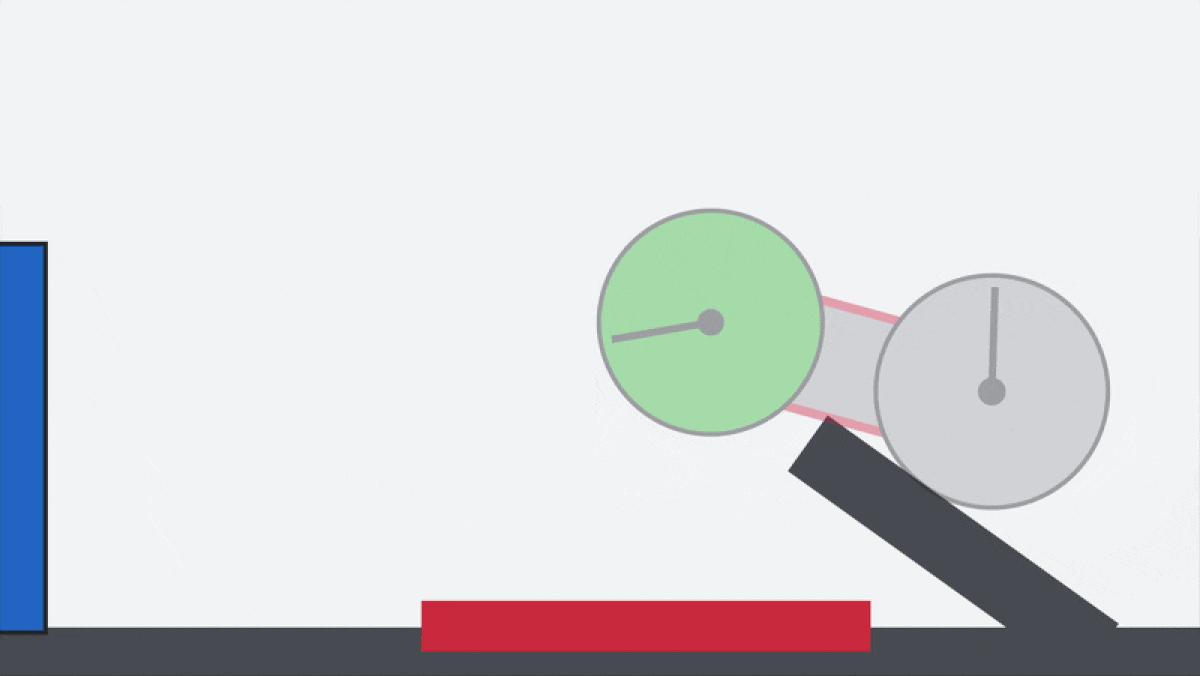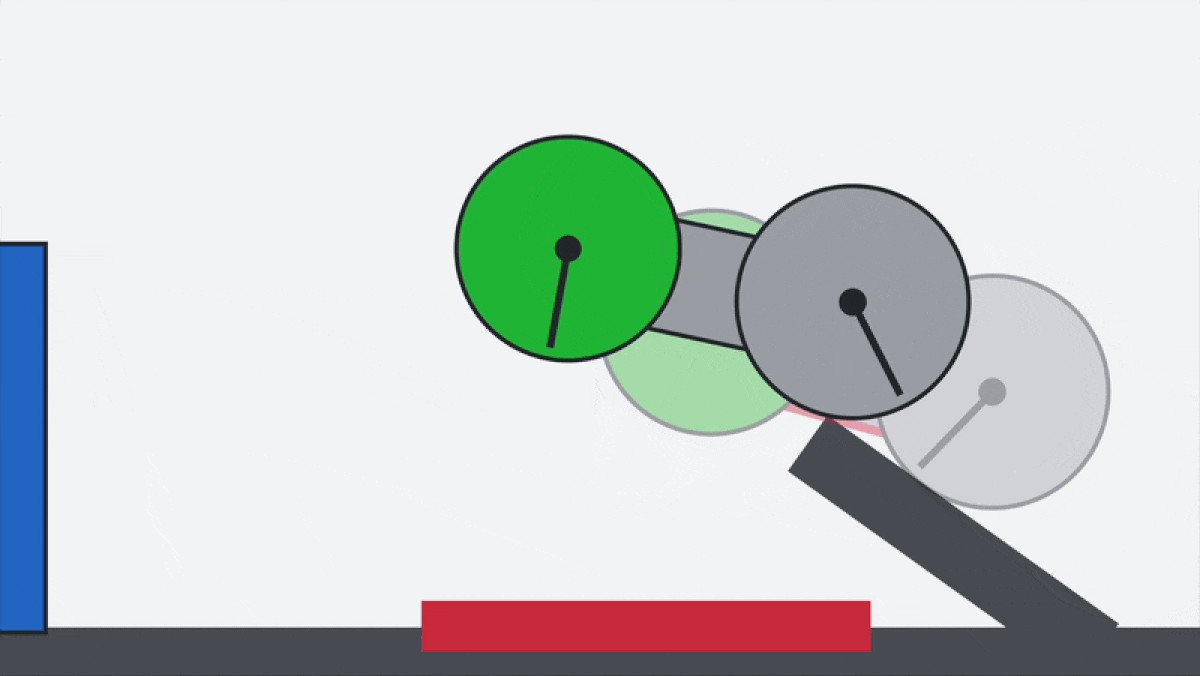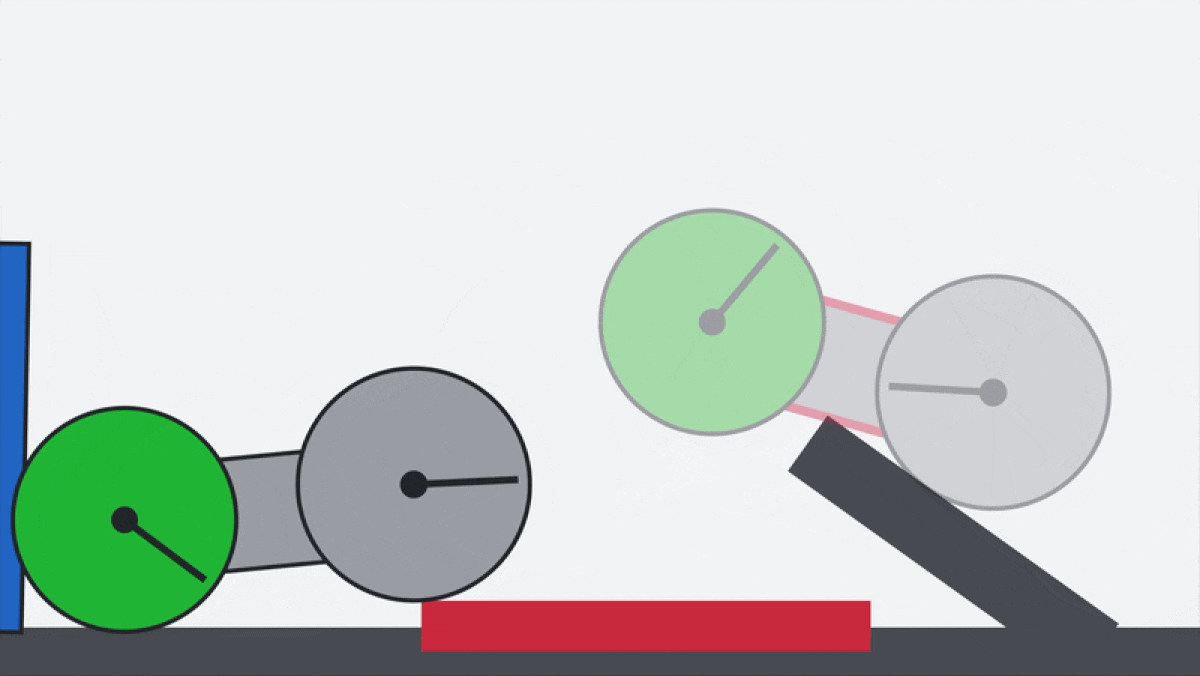
- The authors trained a vanilla neural network (171,000 parameters) to drive a car up a ramp in the Kinetix environment but suspended the training when the car failed to climb the ramp. They fed GPT-6 Astra a description of the problem, the goal, the model weights, and one of the actions the model took during a failed run. GPT-6 Astra edited 3.5 percent of the vanilla neural network’s weights, enabling it to succeed in all 1,024 attempts.
- They gave GPT-6 Astra the rules and source code of a game (specifically Breakout, Seaquest, or Asterix) and a 20,000-parameter network whose weights were initialized to 0, and asked it to generate a model that would play the game. They trained networks of the same size and type for comparison. The generated models achieved higher scores than the manually trained ones at 100 million training steps. However, the trained models were more competitive at 500 million training steps: Of the three games, Astra led on one, roughly tied on one, and lost on the third.
- GPT-6 Astra, given Qwen3.5-0.8B’s weights, a tool to run it, and the training set for the MATH-500 and GSM8K math benchmarks, was asked to improve its benchmark performance. It found that Qwen3.5-0.8B often looped, filling its context window unnecessarily, and modified 0.016 percent of the weights. The change boosted performance on MATH-500 from 7.9 percent to 48.1 percent.
Yes, but: Not all case studies yielded positive results. Asking GPT-6 Astra to improve Gemma 3 270M’s math performance did not work. GPT-6 Astra didn’t find any looping or other obvious issue, and so it was unable to improve the Gemma 3 270M’s performance.
Why it matters: These results are proofs of concept that have not been shown to extend to more diverse LLMs and target models. However, they show how LLMs could be used in building models. They might improve interpretability, enabling us to better understand the networks we build. Or they might facilitate network editing or generation, making it possible to diagnose and fix obvious issues or accelerate training.
We're thinking: If neural network editing holds true at larger scales, this holds massive promise: It’s much cheaper to run a network once than to fine-tune one.